TL;DR
A local LLM is a large language model that runs on your own servers, workstations or private cloud rather than through a public AI service, so prompts and documents never leave infrastructure you control. For UK businesses it makes most sense where data is highly sensitive, usage is heavy and predictable, or clients demand that information stays in-house. For most general tasks, a well-contracted cloud AI service is still cheaper and more capable.
Last updated: 7 October 2026
Interest in running a local LLM has grown quickly as AI use spreads across UK firms. The Office for National Statistics reported in January 2026 that around a quarter of UK businesses were using some form of AI, up 15 percentage points since the question was first asked. As usage grows, so do the questions boards ask about where their data goes.
Open-weight models from Meta, Mistral, Alibaba and others can now be downloaded and run on a single well-specified server, or even a powerful laptop. That has turned a local LLM from a research project into a realistic option for an IT director at a scale-up. The question is no longer whether it can be done, but when it is worth doing.
This guide explains what a local LLM is, when on-premise beats cloud, what it really costs, and how to decide whether your business should run one.
What is a local LLM?
A large language model is the technology behind tools such as ChatGPT, Copilot and Gemini. Normally you use one through a provider's service: your prompt travels over the internet, is processed in the provider's data centre, and the answer comes back. A local LLM reverses that. You download the model weights and run the model on hardware you own or a private environment you control.
Popular tools for running models locally include Ollama, LM Studio and vLLM, which let a technical team serve a model to staff through a chat interface or connect it to internal systems. Many open-weight models are released under permissive licences such as Apache 2.0, though some carry their own community licence terms that your legal team should check before commercial use.
Local models are usually smaller than the leading cloud models, so they are less capable at complex reasoning. For focused tasks such as summarising documents, classifying emails, drafting standard text or searching internal knowledge, a well-chosen local LLM is often good enough.
When a local LLM beats cloud AI
A local LLM earns its place in a few clear situations:
- Highly sensitive data — legal, medical, defence, financial or HR material where clients or regulators expect it never to leave your environment.
- Contractual restrictions — client agreements that ban sending their data to third-party AI providers.
- Heavy, predictable volumes — processing thousands of documents a day, where per-use cloud charges add up faster than fixed hardware costs.
- Offline or low-latency needs — factory floors, field sites or secure networks without reliable internet access.
- Control over change — a fixed model version that will not alter behaviour when a provider updates its service.
- Customisation — fine-tuning a model on your own documents or terminology without sharing them externally.
The trade-offs and real costs
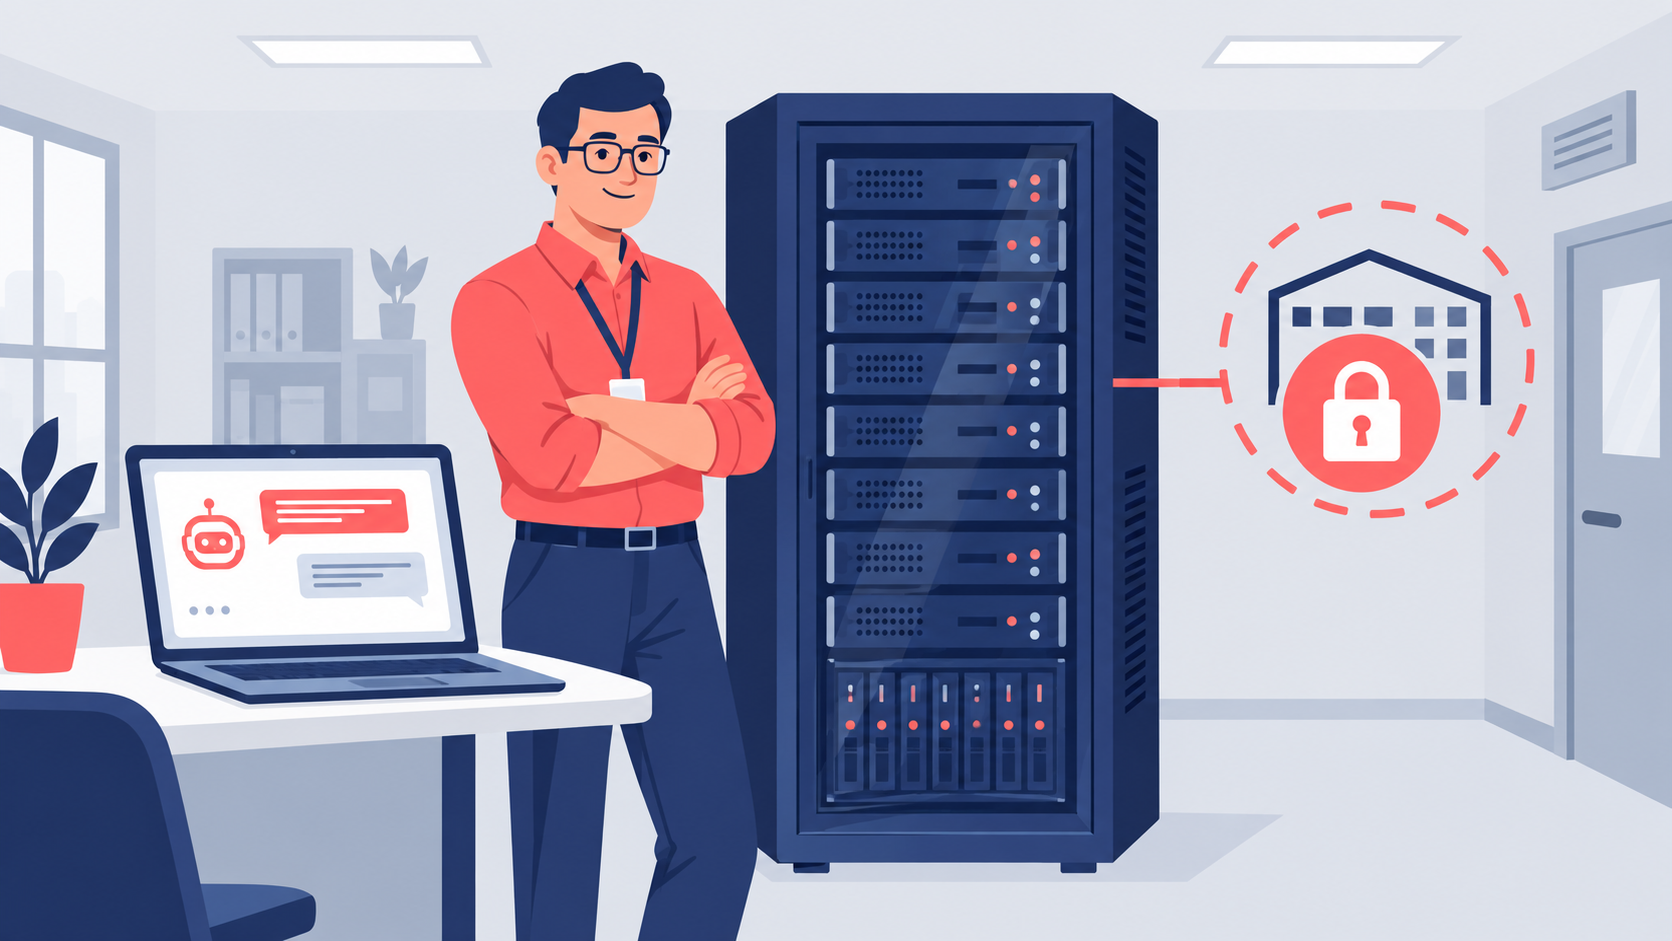
Running a local LLM is not free just because the model is. A capable server with one or two modern GPUs typically costs several thousand to tens of thousands of pounds, before power, cooling, support and replacement. Someone has to install, secure, patch and monitor it, and that skill is scarce in most scale-ups.
Security does not look after itself either. The National Cyber Security Centre's guidance on large language models highlights risks such as prompt injection and inaccurate output that apply wherever a model runs. A local LLM connected to internal files needs proper access controls, logging and testing. And it is still subject to UK GDPR: the ICO's AI guidance applies to any processing of personal data, wherever the model runs.
Picture a 200-person engineering firm that wants AI to search 20 years of project files containing client drawings. Its contracts forbid sharing that data with third parties. A local LLM on a single GPU server, connected to the document store with existing permissions, gives engineers fast answers while the data stays in-house. The same firm uses a contracted cloud assistant for everyday emails and meeting notes, because there is no reason to run that locally.
How to decide whether you need a local LLM
Start with the use case, not the technology. List the tasks where staff want AI help, the data each one touches, and any client or regulatory restrictions. Most tasks will be fine on an approved cloud service with proper data terms. The few that are not are your candidates for a local LLM.
Then run a short, contained pilot: one model, one use case, one team, with clear measures for quality, speed and cost. Compare the results with an enterprise cloud option before committing to hardware. If staff are already using unapproved tools, deal with that first; our guide to shadow AI in UK businesses explains how.
When choosing help, look for someone who understands infrastructure, security and AI together, can show sector experience, starts quickly and works on a fixed scope with no long-term tie-in. Our AI consultancy service draws on CIOs and data and AI directors from our bench who have made exactly these decisions.
Frequently asked questions
Is a local LLM more secure than ChatGPT or Copilot?
What hardware do you need to run a local LLM?
Are open-weight models free to use commercially?
Does UK GDPR still apply to a local LLM?
Is a local LLM cheaper than cloud AI?
Need help deciding on a local LLM?
Leadership Services gives UK scale-ups access to a bench of 500+ senior directors, including CIOs and data and AI leaders who can assess whether a local LLM or a cloud service fits your needs and run a contained pilot. Engagements start from £1,795 per month, begin within one week and have no long-term tie-ins — get in touch and we will respond the same working day.